Oasis / Voice-Driven Emotion Network Paradigm
A computational psychometrics research paradigm and task pipeline turning spoken daily reflection into computable emotion concept networks, developed alongside a 35-page psychometric study protocol.
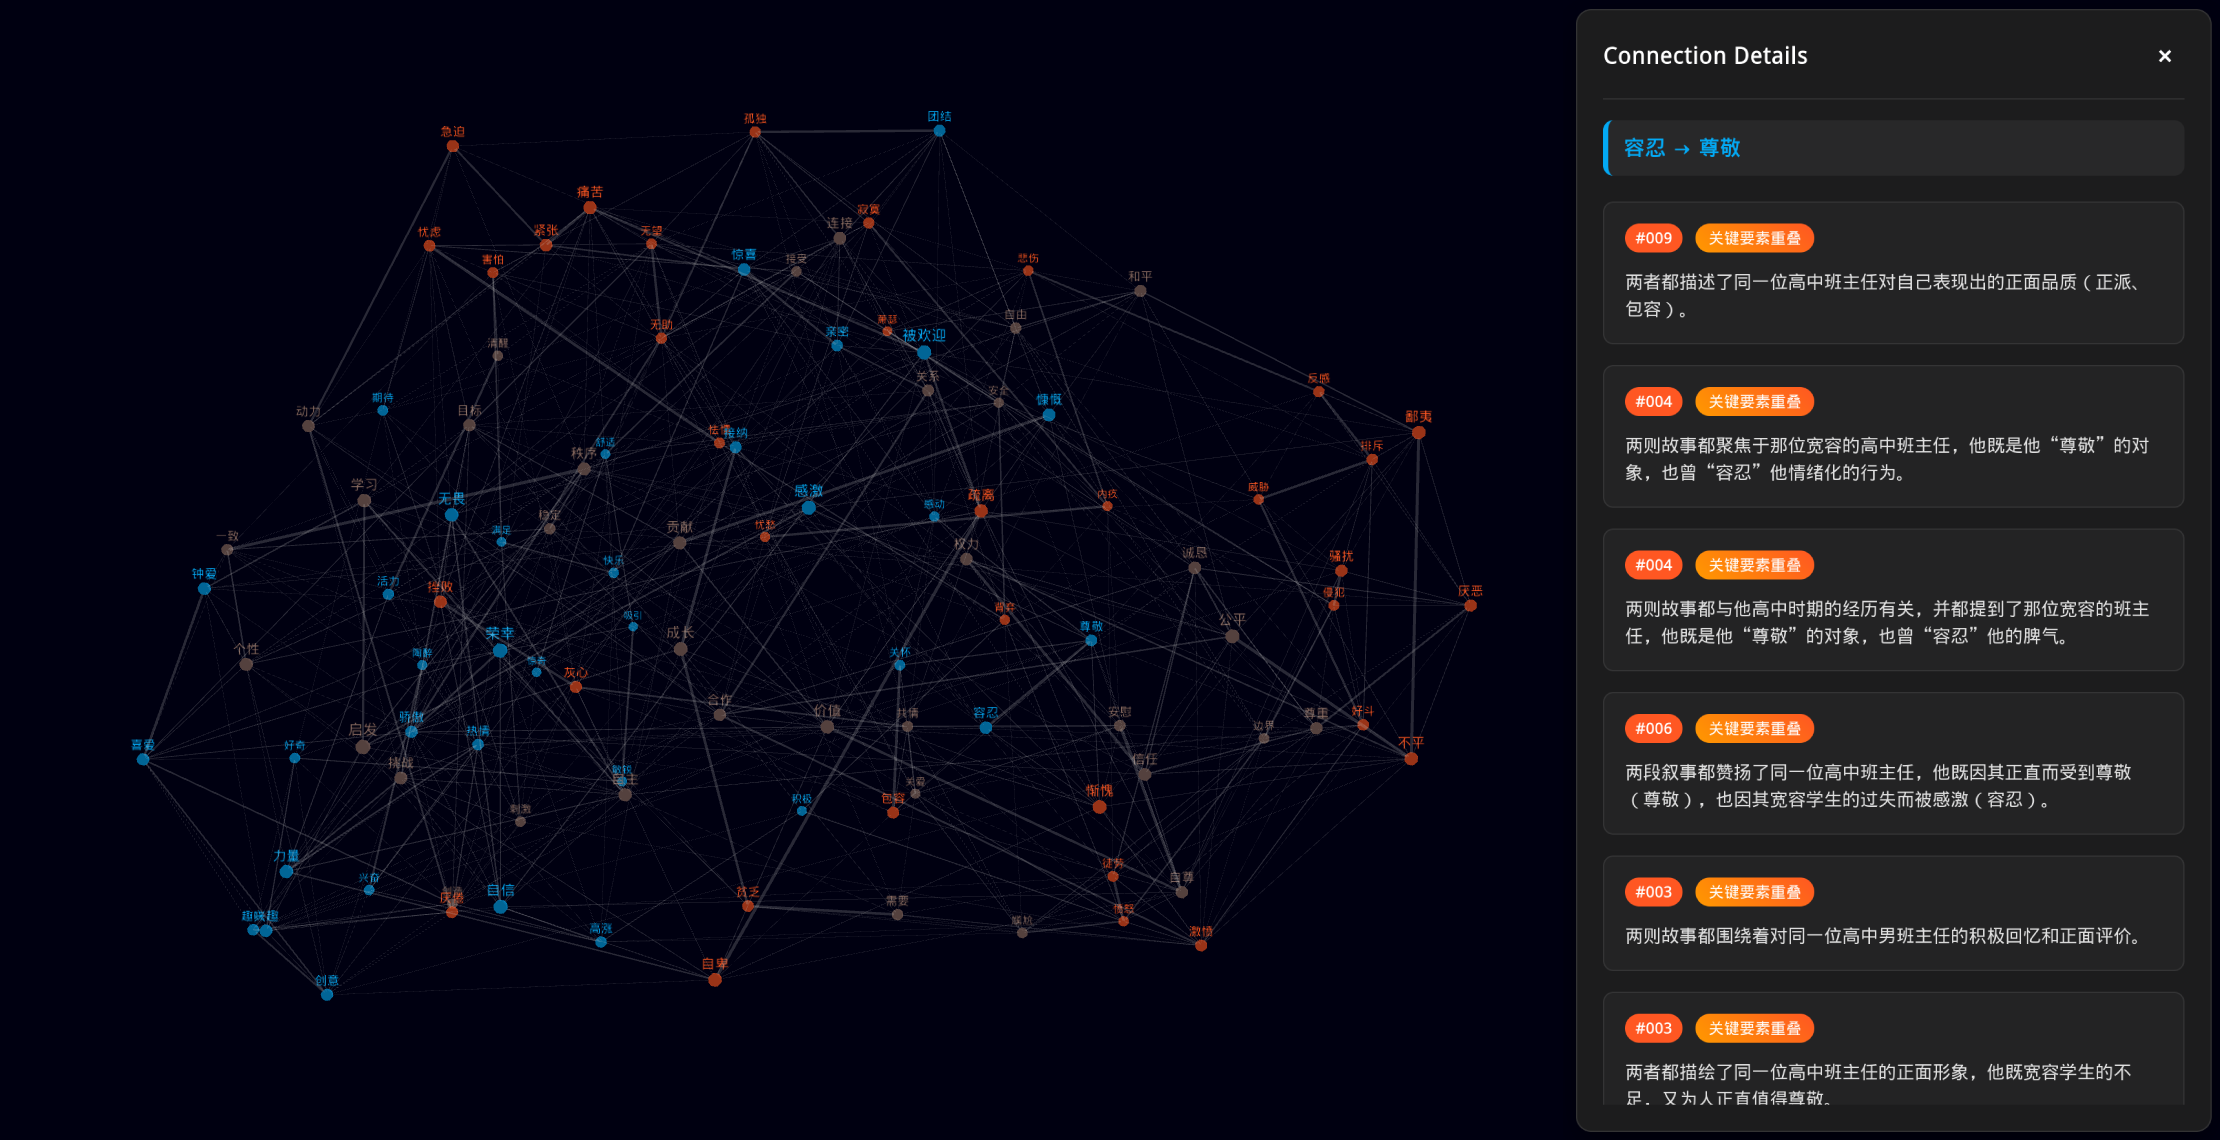
TL;DR
- Addressed the ecological validity gap in affective measurement: standard scales (PHQ-9, GAD-7) rely on retrospective estimation and omit context, while open-ended journals resist automated quantification.
- Formulated a formal psychometric protocol grounded in Barrett’s Theory of Constructed Emotion, pairing the Chinese Affective Words System (CAWS) with three custom codebooks covering lexicon, trigger context, and narrative relations.
- Engineered a complete local-first processing pipeline in Rust (Axum, Diesel, Tokio) featuring local Whisper speech-to-text, multi-perspective LLM extraction, dynamic questionnaire synthesis, and a clinical review portal.
Role
Paradigm design, architecture, full-stack engineering
Theoretical Base
Constructed Emotion (Barrett), CAWS Lexicon
Tech Stack
Rust, Axum, SQLite, whisper-rs, React Router
Artifacts
35-page study protocol, 3 codebooks, pipeline MVP
THE MEASUREMENT GAP
Why static rating scales miss affective dynamics
Clinical and educational psychology rely heavily on standardized self-report batteries. While statistically robust for population screening, these tools flatten dynamic human experience into static ordinal numbers, missing the causal chain between daily triggers, emotional appraisal, and unmet psychological needs.
Standardized Questionnaires (PHQ-9 / GAD-7 / PANAS)
Strength
High psychometric norm comparability; quick administration (2 to 5 minutes).
Limitation
Low ecological validity; susceptible to recall bias; collapses multi-layered emotional conflict into a single numerical score without context.
Unstructured Diary Narratives
Strength
Preserves real-world ecological context, specific life events, and natural coping language.
Limitation
Resists quantitative aggregation; manual qualitative coding requires trained coders and weeks of delay, preventing timely intervention.
The Combinatorial Bottleneck
Mapping pairwise interactions across a comprehensive vocabulary of 361 emotion concepts would require 129,960 questionnaire comparisons. No human participant can sustain such an evaluation. By combining daily spoken narratives with structured qualitative codebooks, language models can extract recurring emotion-context connections naturally, resolving the tension between psychological depth and evaluation feasibility.
PSYCHOMETRIC FRAMEWORK
Modeling emotion as an interconnected concept network
Grounded in Lisa Feldman Barrett’s Theory of Constructed Emotion (2017), Oasis views feelings not as hardwired biological triggers, but as situated cognitive categories constructed from somatic signals, context, and learned concepts. The protocol operationalizes this through three rigorous codebooks.
Lexicon Layer
Chinese Affective Words System (CAWS)
Curated library of 500 to 800 two-character Chinese emotion terms, filtered by high familiarity ratings (>= 6/9) and tagged with normative valence and arousal benchmarks.
Context Node Codebook
Trigger Context Taxonomy
Multi-level classification of daily life events spanning individual pressures (work, study, health), family dynamics, and broader social interactions.
Narrative Edge Codebook
Relational & Needs Framework
Directed relational edges defining causal links, emotional escalation, coping mechanisms, and underlying psychological needs (such as safety, autonomy, and belonging).
Triad Structure & Five Edge Dimensions
Every narrative entry is anchored by a balanced triad: one positive emotion, one negative emotion, and one underlying psychological need. Relational edges between entries are coded across five explicit dimensions:
- 1. Thematic similarity across shared life domains
- 2. Chronological or causal sequences tracking affective evolution
- 3. Psychodynamic tension, internal conflict, and defense mechanisms
- 4. Interpersonal relationship dynamics with significant individuals
- 5. Overlapping key entities (shared people, places, or artifacts)
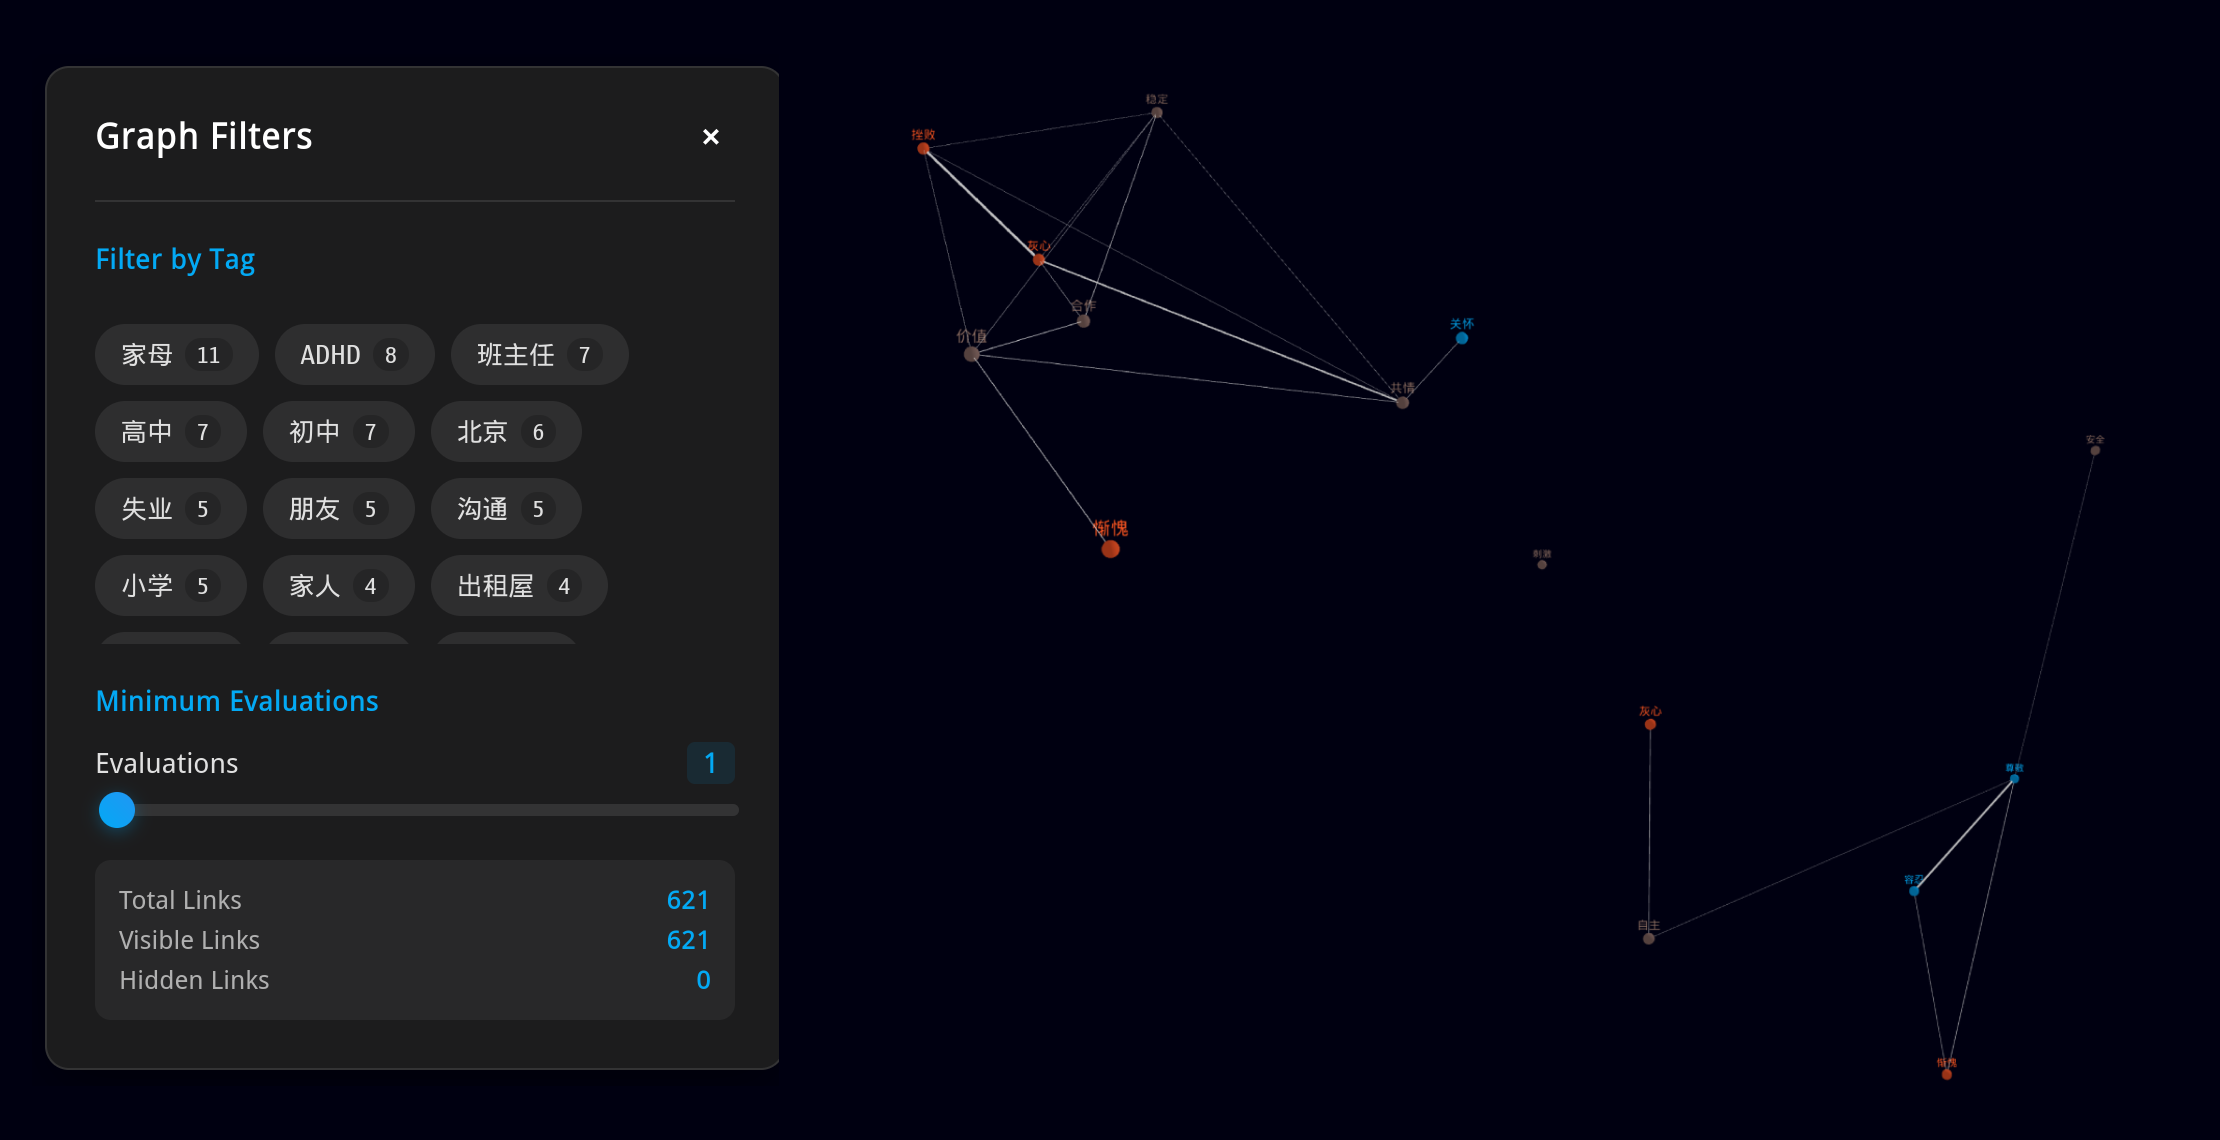
Tag-filtered sub-networks: selecting tags such as specific environments or developmental milestones isolates interpretable emotional clusters rather than undifferentiated global graphs.
EXPERIMENTAL PROTOCOL
A four-stage controlled daily session
To guarantee data fidelity and ecological validity across longitudinal cohorts (10-day and 20-day tracks), each daily session followed a tightly controlled protocol designed to minimize participant fatigue.
Blind Assessment & Scales
Participants review the previous day’s diary analysis through a double-blind rating interface, evaluating two randomized model outputs on a 5-point Likert accuracy scale before completing rotating standard batteries (PHQ-9, GAD-7).
Mindful Settling
Standardized audio-guided breathing resets working memory and clears cognitive interference from previous analytical tasks, guiding attention back to the day’s most salient personal event.
Voice Narration
Spoken audio input (minimum 3 minutes) captures spontaneous affective expression with significantly lower friction than typing. Whisper performs local transcription, and an LLM cleans disfluencies for participant confirmation.
Immediate Valuation
Participants score the overall experience on 5-point Valence (pleasantness) and Arousal (intensity) scales, establishing an unprimed subjective ground truth for subsequent model evaluation.
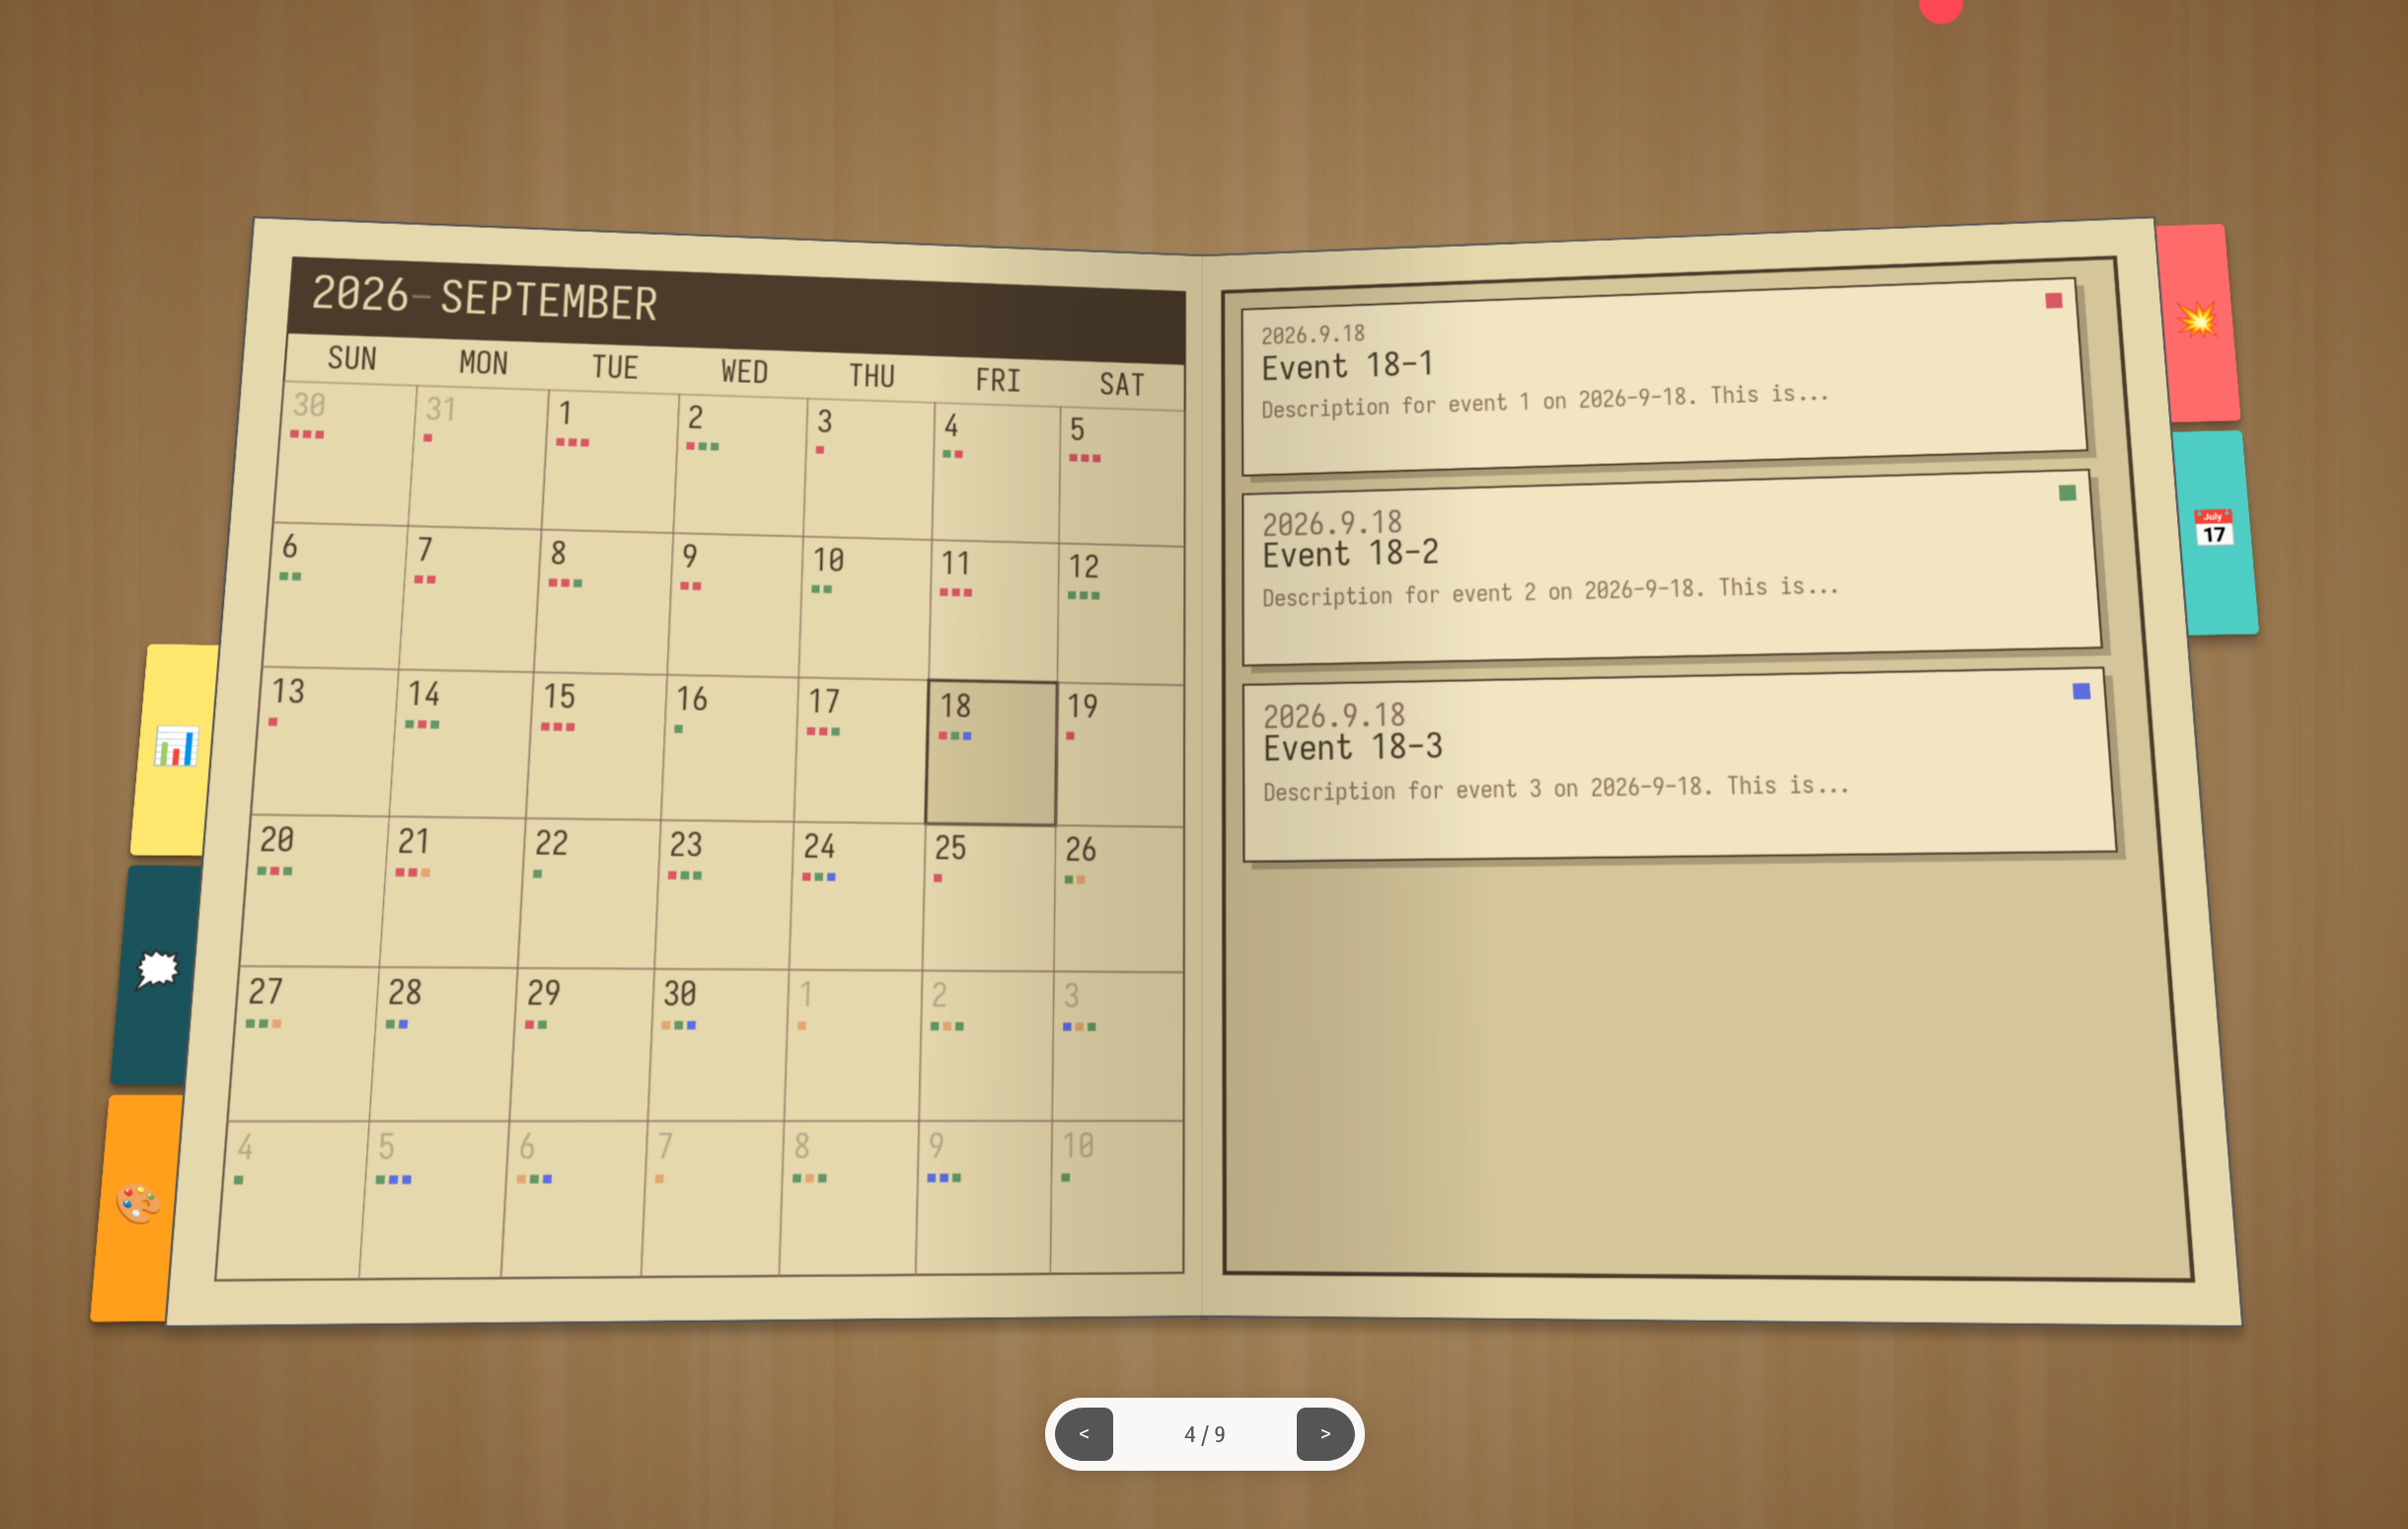
Diary Ingestion Prototype: Daily Calendar & Event Logging
Color-coded affective anchors mark events across calendar days, structuring the raw narrative feed before pipeline ingestion.
SYSTEM ARCHITECTURE
The RAG Pipeline System
Each reflection session coordinates speech transcription, multi-perspective qualitative extraction, and questionnaire generation. The backend executes these stages as an asynchronous task graph, balancing analysis depth, participant safety, and system responsiveness.
End-to-End Data Flow
Speech Ingestion
Transcribes participant voice recordings locally, keeping audio buffers within the on-premises server boundary.
Tri-Perspective Extraction
Evaluates emotional, cognitive, and critical aspects concurrently across independent worker threads.
Thematic Synthesis
Combines the multi-perspective outputs into a coherent narrative report highlighting core unmet needs.
Gated Questionnaire
Stages generated reflection prompts in a quarantine queue for researcher inspection before unlocking for participants.
Key Architectural Decisions & Trade-offs
Concurrent Analysis Fan-Out & Aggregation
The Constraint
Prompting a single model to evaluate emotional, cognitive, and critical angles simultaneously yielded homogenized answers. Running three separate evaluations sequentially tripled pipeline latency.
The Architectural Choice
The task engine fans out three independent sub-tasks in parallel under a shared session run, then collects and merges their outputs before invoking the final synthesis model.
The Trade-off
Adds sub-task lifecycle tracking and synchronization complexity, but preserves distinct analytical perspectives without linear latency accumulation.
Two-Stage Review Quarantine & Inline Editing
The Constraint
AI-generated reflection questions cannot be shown directly to participants without clinical review, but authoring custom questions by hand creates an unsustainable research bottleneck.
The Architectural Choice
Generation is decoupled from delivery. Candidate questions are staged in an approval queue where researchers can inspect items, adjust wording or scale ranges inline, and approve them before they enter the active questionnaire catalog.
The Trade-off
Questionnaire delivery becomes an asynchronous step rather than immediate, requiring queue state management and role-based reviewer access control.
Differential Audio Follow-Up Tasks
The Constraint
Participants frequently clarify an emotion label or add context after reading their initial summary. Re-running the full audio ingestion and analysis pipeline wastes compute and risks altering accepted sections.
The Architectural Choice
Supplemental voice notes are transcribed separately and fed alongside the existing session summary into a targeted follow-up task, patching only the disputed narrative sections.
The Trade-off
Introduces branched workflows outside the primary linear task graph, requiring state reconciliation when storing session revisions.
CLINICAL SAFETY & ETHICS
Three-tier risk intervention protocol
Processing unscripted affective diaries carries acute clinical and ethical responsibilities. The research protocol established a comprehensive crisis SOP approved under standard institutional review guidelines.
Trigger Criteria
Passive avoidance language (e.g. chronic exhaustion, isolation feelings).
Protocol Action
Automated platform flag; on-duty researcher reviews raw entry within 24 hours to monitor progression.
Trigger Criteria
Self-harm thoughts without explicit timetable or executable plan.
Protocol Action
Immediate researcher alert; outreach within 48 hours for Columbia Suicide Severity Rating Scale (C-SSRS) evaluation.
Trigger Criteria
Explicit plans, means, or immediate intent disclosed in audio or text.
Protocol Action
Emergency response within 1 hour; activation of pre-authorized emergency contacts and direct handoff to crisis centers.
Privacy & De-Identification Safeguards
Personal names, school names, specific locations, and exact dates were scrubbed by a dedicated de-identification prompt before records reached persistent database tables. Children cohorts operated under dedicated child assent procedures and mandatory reporting protocols for domestic safety concerns.
EVALUATION CRITERIA
Psychometric reliability instead of vanity metrics
Because Oasis is a scientific measurement framework rather than a consumer ad-supported app, success is evaluated through psychometric reliability, construct validity, and network topology analysis.
Reliability: LLM Consistency
Fleiss’ Kappa > 0.80 & Kendall’s W
Each diary entry is analyzed 30 times under identical prompt conditions to verify vocabulary stability, top-term ranking consistency, and Poisson distribution fit.
Validity: Convergent Benchmarking
Pearson r > 0.40 against Ground Truth
Correlating normative valence and arousal values of extracted CAWS terms against participants’ immediate post-diary self-ratings and concurrent PHQ-9 batteries.
Network Topology: Graph Metrics
Small-World Index & Centrality
Using graph analysis to quantify degree, betweenness, and modularity, determining whether emotional concept clusters exhibit scale-free small-world characteristics.
Developmental and Clinical Comparison Design
The study protocol defines a cross-sectional comparison across elementary cohorts (grades 1 to 6) and university students, testing whether network edge density correlates with difficulties in emotion regulation (DERS scores) and how vocabulary granularity matures over development.